

[May 25, 2024] Reliable DP-100 Exam Tips Test Pdf Exam Material
New 2024 DP-100 Test Tutorial (Updated 410 Questions)
Microsoft DP-100 (Designing and Implementing a Data Science Solution on Azure) Exam is a certification exam that measures a candidate's ability to design and implement data science solutions using Microsoft Azure technologies. DP-100 exam is intended for data scientists, data engineers, and other professionals who work with data and want to validate their skills and knowledge in using Azure to solve data-related problems.
The DP-100 exam is designed to test candidates' knowledge and skills in various areas related to data science, such as data exploration and preparation, modeling, feature engineering, and machine learning. To pass the exam, candidates must demonstrate their ability to design and implement data science solutions using Azure services such as Azure Machine Learning, Azure Databricks, and Azure HDInsight, among others.
NEW QUESTION # 15
You are performing a classification task in Azure Machine learning Studio.
You must prepare balanced testing and training samples based on a provided data set.
Warning samples based on a provided data set.
You need to split the data with a 0.75:0.25.
Which value should you use for each parameter? To answer, select the appropriate options m the answer area.
NOTE: Each correct selection is worth one point.
Answer:
Explanation: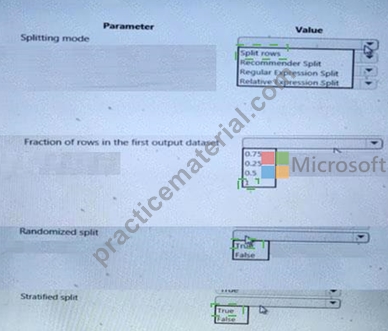
NEW QUESTION # 16
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You are analyzing a numerical dataset which contains missing values in several columns.
You must clean the missing values using an appropriate operation without affecting the dimensionality of the feature set.
You need to analyze a full dataset to include all values.
Solution: Calculate the column median value and use the median value as the replacement for any missing value in the column.
Does the solution meet the goal?
- A. Yes
- B. No
Answer: B
Explanation:
Explanation
Use the Multiple Imputation by Chained Equations (MICE) method.
References:
https://www.ncbi.nlm.nih.gov/pmc/articles/PMC3074241/
https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/clean-missing-data
NEW QUESTION # 17
You are developing a machine learning model.
You must inference the machine learning model for testing.
You need to use a minimal cost compute target
Which two compute targets should you use? Each correct answer presents a complete solution.
NOTE: Each correct selection is worth one point
- A. Azure Container Instances
- B. Remote VM
- C. Azure Machine Learning Kubernetes
- D. Local web service
- E. Azure Databricks
Answer: A,D
NEW QUESTION # 18
You have the following Azure subscriptions and Azure Machine Learning service work*spaces:
You need to obtain a reference to the mi-protect workspace
Solution: Run the following Python code.
Does the solution meet the goal?
- A. No
- B. Yes
Answer: B
NEW QUESTION # 19
You register the following versions of a model.
You use the Azure ML Python SDK to run a training experiment. You use a variable named run to reference the experiment run.
After the run has been submitted and completed, you run the following code:
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.
Answer:
Explanation: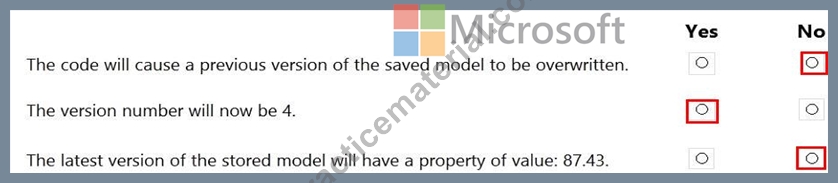
Reference:
https://docs.microsoft.com/en-us/azure/machine-learning/how-to-deploy-and-where
NEW QUESTION # 20
You are running a training experiment on remote compute in Azure Machine Learning.
The experiment is configured to use a conda environment that includes the mlflow and azureml-contrib-run packages.
You must use MLflow as the logging package for tracking metrics generated in the experiment You need to complete the script for the experiment How should you complete the code? To answer, select the appropriate options in the answer area.
Answer:
Explanation: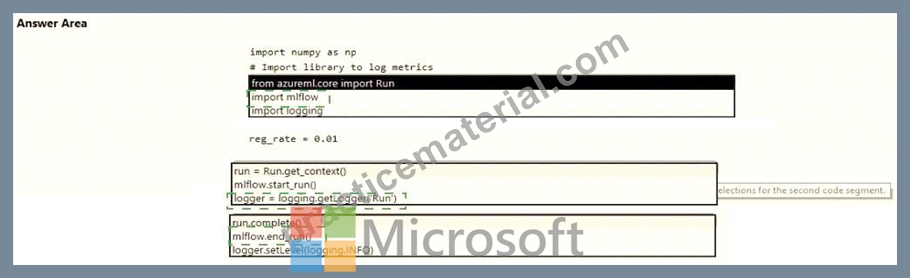
NEW QUESTION # 21
You create an Azure Machine Learning workspace. The workspace contains a dataset named sample.dataset, a compute instance, and a compute cluster. You must create a two-stage pipeline that will prepare data in the dataset and then train and register a model based on the prepared dat a. The first stage of the pipeline contains the following code:
You need to identify the location containing the output of the first stage of the script that you can use as input for the second stage. Which storage location should you use?
- A. workspacefi lest ore datastore
- B. workspaceblobstore datastore
- C. compute instance
Answer: C
NEW QUESTION # 22 
For each of the following statements, select Yes if the statement is true. Otherwise, select No. NOTE: Each correct selection is worth one point.
Answer:
Explanation:
NEW QUESTION # 23
You configure a Deep Learning Virtual Machine for Windows.
You need to recommend tools and frameworks to perform the following:
Build deep rwur.il network (DNN) models.
Perform interactive data exploration and visualization.
Which tools and frameworks should you recommend? To answer, drag the appropriate tools to the correct tasks. Each tool may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
NEW QUESTION # 24
You need to build a feature extraction strategy for the local models.
How should you complete the code segment? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
NEW QUESTION # 25
You need to set up the Permutation Feature Importance module according to the model training requirements.
Which properties should you select? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
Answer:
Explanation: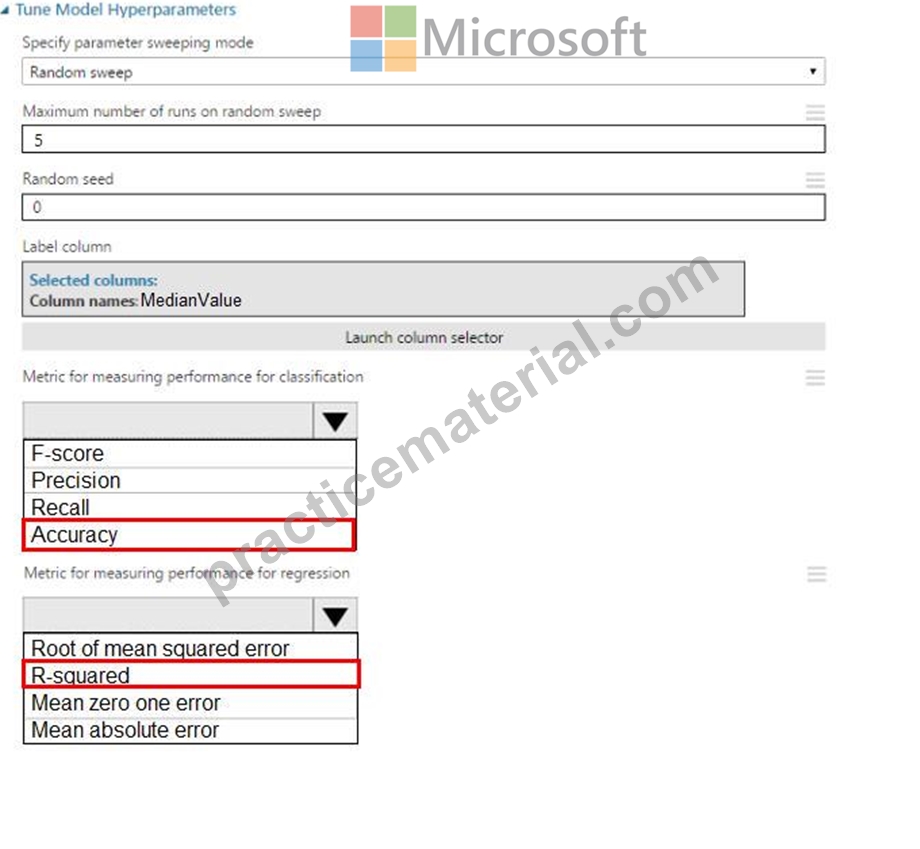
Explanation:
Box 1: Accuracy
Scenario: You want to configure hyperparameters in the model learning process to speed the learning phase by using hyperparameters. In addition, this configuration should cancel the lowest performing runs at each evaluation interval, thereby directing effort and resources towards models that are more likely to be successful.
Box 2: R-Squared
NEW QUESTION # 26
You have an Azure Machine Learning workspace that contains a training cluster and an inference cluster.
You plan to create a classification model by using the Azure Machine Learning designer.
You need to ensure that client applications can submit data as HTTP requests and receive predictions as responses.
Which three actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.
Answer:
Explanation: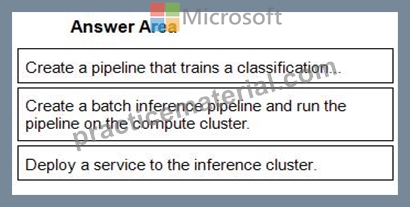
1 - Create a pipeline that trains a classification...
2 - Create a batch inference pipeline and run the pipeline on the compute cluster.
3 - Deploy a service to the inference cluster.
NEW QUESTION # 27
You are creating an experiment by using Azure Machine Learning Studio.
You must divide the data into four subsets for evaluation. There is a high degree of missing values in the data.
You must prepare the data for analysis.
You need to select appropriate methods for producing the experiment.
Which three modules should you run in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.
NOTE: More than one order of answer choices is correct. You will receive credit for any of the correct orders you select.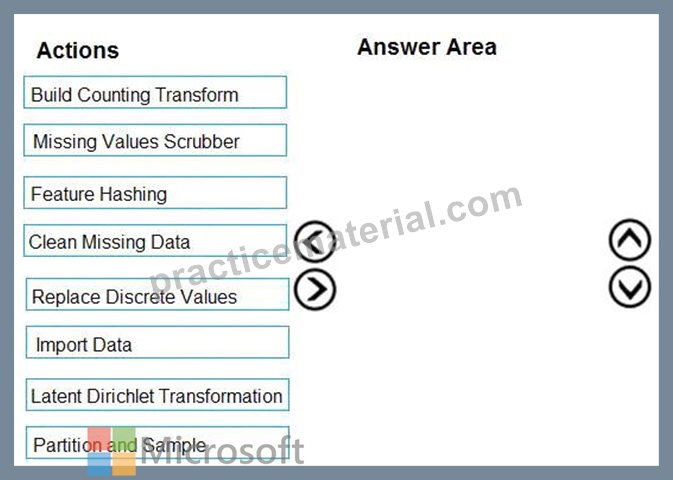
Answer:
Explanation: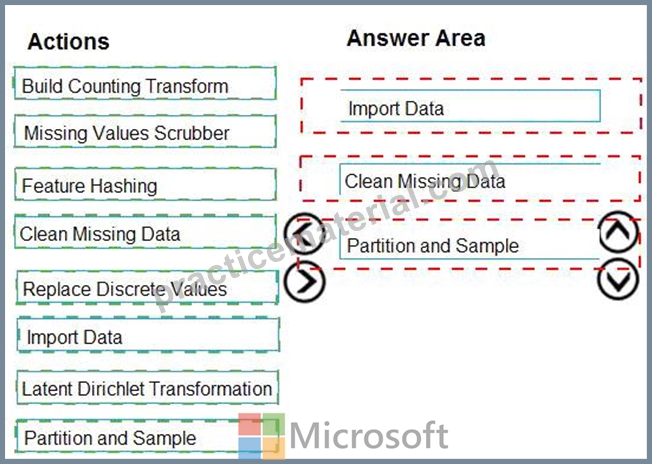
Explanation
The Clean Missing Data module in Azure Machine Learning Studio, to remove, replace, or infer missing values.
NEW QUESTION # 28
You need to configure the Permutation Feature Importance module for the model training requirements.
What should you do? To answer, select the appropriate options in the dialog box in the answer area.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
Explanation
Box 1: 500
For Random seed, type a value to use as seed for randomization. If you specify 0 (the default), a number is generated based on the system clock.
A seed value is optional, but you should provide a value if you want reproducibility across runs of the same experiment.
Here we must replicate the findings.
Box 2: Mean Absolute Error
Scenario: Given a trained model and a test dataset, you must compute the Permutation Feature Importance scores of feature variables. You need to set up the Permutation Feature Importance module to select the correct metric to investigate the model's accuracy and replicate the findings.
Regression. Choose one of the following: Precision, Recall, Mean Absolute Error , Root Mean Squared Error, Relative Absolute Error, Relative Squared Error, Coefficient of Determination References:
https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/permutation-feature-importan
NEW QUESTION # 29
You use the Azure Machine Learning service to create a tabular dataset named training.data. You plan to use this dataset in a training script.
You create a variable that references the dataset using the following code:
training_ds = workspace.datasets.get("training_data")
You define an estimator to run the script.
You need to set the correct property of the estimator to ensure that your script can access the training.data dataset Which property should you set?
A)
B)
C)
D)
- A. Option D
- B. Option B
- C. Option A
- D. Option C
Answer: C
Explanation:
Explanation
Example:
# Get the training dataset
diabetes_ds = ws.datasets.get("Diabetes Dataset")
# Create an estimator that uses the remote compute
hyper_estimator = SKLearn(source_directory=experiment_folder,
inputs=[diabetes_ds.as_named_input('diabetes')], # Pass the dataset as an input compute_target = cpu_cluster, conda_packages=['pandas','ipykernel','matplotlib'], pip_packages=['azureml-sdk','argparse','pyarrow'], entry_script='diabetes_training.py') Reference:
https://notebooks.azure.com/GraemeMalcolm/projects/azureml-primers/html/04%20-%20Optimizing%20Model
NEW QUESTION # 30 
You must use the Azure Machine Learning SDK to interact with data and experiments in the workspace.
You need to configure the config.json file to connect to the workspace from the Python environment.
Which two additional parameters must you add to the config.json file in order to connect to the workspace?
Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
- A. resource_group
- B. Login
- C. Key
- D. region
- E. subscription_Id
Answer: D,E
NEW QUESTION # 31
You are developing a machine learning, experiment by using Azure. The following images show the input and output of a machine learning experiment:
Use the drop-down menus to select the answer choice that answers each question based on the information presented in the graphic.
NOTE: Each correct selection is worth one point.
Answer:
Explanation: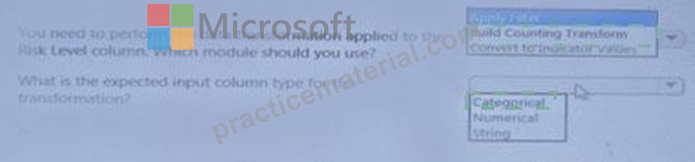
NEW QUESTION # 32
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You plan to use a Python script to run an Azure Machine Learning experiment. The script creates a reference to the experiment run context, loads data from a file, identifies the set of unique values for the label column, and completes the experiment run:
from azureml.core import Run
import pandas as pd
run = Run.get_context()
data = pd.read_csv('data.csv')
label_vals = data['label'].unique()
# Add code to record metrics here
run.complete()
The experiment must record the unique labels in the data as metrics for the run that can be reviewed later.
You must add code to the script to record the unique label values as run metrics at the point indicated by the comment.
Solution: Replace the comment with the following code:
run.log_table('Label Values', label_vals)
Does the solution meet the goal?
- A. Yes
- B. No
Answer: B
Explanation:
Instead use the run_log function to log the contents in label_vals:
for label_val in label_vals:
run.log('Label Values', label_val)
Reference:
https://www.element61.be/en/resource/azure-machine-learning-services-complete-toolbox-ai
NEW QUESTION # 33
You create a binary classification model to predict whether a person has a disease.
You need to detect possible classification errors.
Which error type should you choose for each description? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
Answer:
Explanation: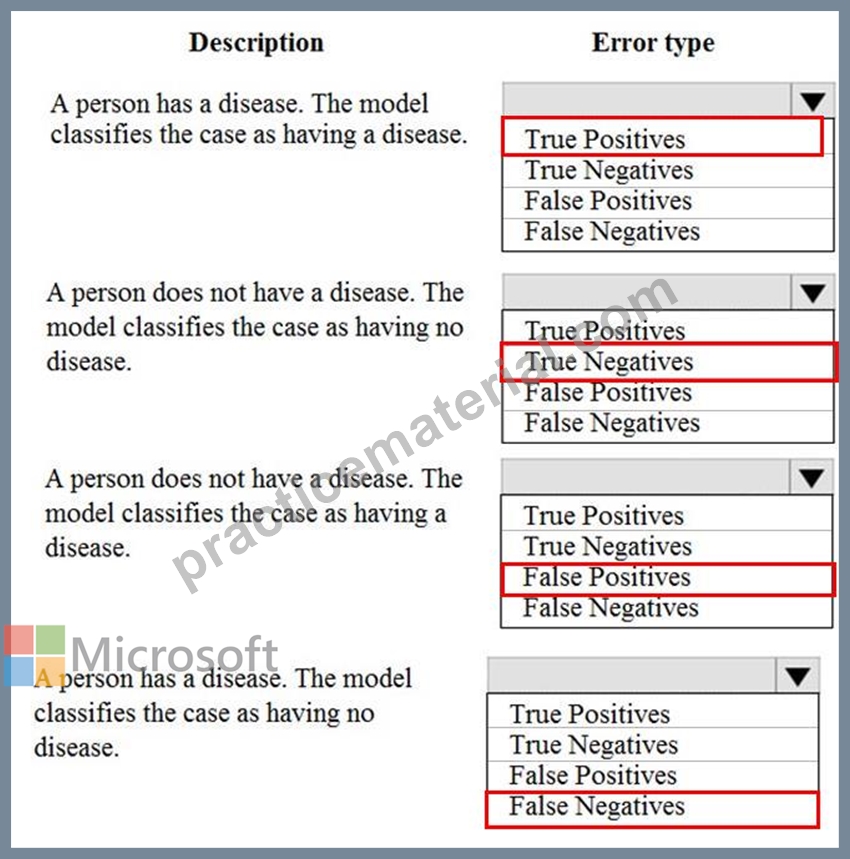

Reference:
https://developers.google.com/machine-learning/crash-course/classification/true-false-positive-negative
NEW QUESTION # 34
You use Azure Machine Learning to train a machine learning model.
You use the following training script in Python to perform logging:
You must use a Python script to define a sweep job.
You need to provide the primary metric and goal you want hyperparameter tuning to optimize.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
NEW QUESTION # 35
......
DP-100 Cert Guide PDF 100% Cover Real Exam Questions: https://www.practicematerial.com/DP-100-exam-materials.html
DP-100 Exam Questions Dumps, Selling Microsoft Products: https://drive.google.com/open?id=1qi3Pn4CpM1oM4o_yw45_GxjO57A0FuHH
